


Scaling modern tech operations can feel like a difficult balancing act. Many growing companies struggle with the cost and time needed to build a full internal department from scratch.
Fortunately, there is a smarter path forward. Partnering with an outsourced DevOps team gives expert help with security, scaling, and daily operations without direct hiring.
This guide covers the best ways to how to manage cloud infrastructure effectively while keeping your business agile. We cover access controls, automation, monitoring, and incident response.
You will learn to keep full ownership of your systems while using external talent. Let’s explore a framework for a successful transition.
Table of Contents
Key Takeaways
- Reduce overhead costs by avoiding full-time internal hires.
- Gain immediate access to specialized cloud security expertise.
- Implement robust automation to streamline your daily operations.
- Maintain strict control over access and system permissions.
- Establish clear vendor accountability for incident response.
- Plan a smooth transition to ensure long-term operational success.
Why Outsource DevOps for Cloud Infrastructure
When your internal engineering team spends more time fixing infrastructure than building products, consider a new strategy. Many companies reach a point when environment complexity outgrows internal capacity. DevOps outsourcing lets developers focus on creating customer value.
When in-house cloud management becomes a bottleneck
As your digital footprint expands, maintaining uptime, security, and performance can overwhelm a small team. You might notice your best engineers leaving feature development for server patches or configuration issues. This shift creates a significant drag on your product roadmap and slows your time to market.

How an outsourced DevOps team fills critical skills gaps
Modern cloud operations require diverse skills, which are often hard to find in one hire. By partnering with an external team, you gain experts in automation, security, and scaling. These professionals bring proven workflows that help avoid common pitfalls and speed deployment cycles.
Instead of struggling to recruit and train expensive talent, you can use a team that already works well together. They provide the knowledge needed to manage complex multi-cloud environments effectively. This approach keeps your infrastructure stable as business requirements evolve.
Balancing cost savings with operational accountability
While reducing overhead helps many businesses, it should never reduce quality. True DevOps outsourcing is about optimizing your budget while maintaining strict accountability for your production systems. You must ensure your partner follows clear, measurable service-level objectives.
Cost savings work best when paired with high performance and reliability. By defining clear responsibilities, you keep your team focused on business outcomes, not just keeping the lights on. Remember, the goal is to build a resilient foundation that supports long-term growth without sacrificing control over critical assets.
How to manage cloud infrastructure with an outsourced DevOps team
Successful cloud infrastructure management starts with clear boundaries from day one. When you hire an outside provider, your staff and its team must work in harmony. Clear roles prevent overlapping work and neglected critical systems.

Define ownership across cloud operations and application teams
To learn how to manage cloud infrastructure, first map each team’s specific duties. Your internal team should own application code and business logic. The outsourced team should manage the platform, networking, and security settings.
This separation lets developers innovate faster without handling low-level server maintenance. Clear roles give every part of your environment an owner for its health and performance.
Set measurable service-level objectives and responsibilities
A formal SLA supports a healthy partnership. Set targets for system availability, incident response times, and change implementation speed. These measures define success and hold your provider responsible for system reliability.
Set realistic goals based on your current environment’s complexity. A clear SLA should define critical incidents and routine requests. This prevents confusion during pressure and ensures timely support.
Establish access, communication, and escalation rules
Clear communication rules help you control your cloud environment. Define how the outsourced team accesses your systems and whom they contact during problems. Early rules protect security while keeping operations flexible.
Use a shared responsibility matrix for daily operations
A shared responsibility matrix guides daily tasks. It shows which team handles patching, monitoring, and backup checks. This document prevents missed tasks during shift changes or busy deployments.
| Operational Task | Internal Team | Outsourced DevOps |
|---|---|---|
| Application Code Deployment | Primary | Support |
| Infrastructure Provisioning | Review | Primary |
| Security Patching | Audit | Primary |
| Incident Response | Escalation | First Responder |
Document who approves infrastructure and production changes
Finally, use a strict process to approve production changes. Document who may approve updates so your cloud infrastructure management stays stable and secure. Formal approval for infrastructure changes protects your business from accidental downtime and unauthorized configuration drift.
Choose the Right Outsourced DevOps Engagement Model
Finding the right balance between internal control and outside expertise starts with choosing an engagement model. Your choice shapes how your team uses cloud resources and responds to technical problems. Whether you need full-time oversight or occasional help, choosing the right managed cloud services supports long-term success.

Managed services for continuous cloud operations
This model suits organizations that want to hand off daily maintenance. A full-service partner keeps infrastructure stable, secure, and optimized around the clock. Your internal team can focus on building features instead of managing servers.
Co-managed DevOps for teams with existing engineers
If you already have an internal engineering team, a co-managed DevOps arrangement often works best. Your staff can manage application tasks while the partner handles complex infrastructure and security layers. This partnership creates synergy while both teams share responsibility for uptime and performance.
Project-based support for migrations and infrastructure modernization
Sometimes, you only need specialized help for a specific period. Project-based engagements suit one-time tasks, such as moving to a new cloud provider or upgrading legacy systems. This model provides intense support without a long-term operational commitment.
Compare coverage hours, response times, and on-call availability
Before signing an agreement, clearly define the support scope. Always verify that the service level agreement (SLA) matches your business needs, including 24/7 on-call availability. A mismatch can cause major downtime during critical incidents.
Match the engagement model to business growth and risk
Your choice should change as your company grows. High-growth startups may value speed and flexibility, while established enterprises often focus on risk reduction and compliance. Documenting these needs early helps your partner scale support with your business.
| Model | Best For | Primary Benefit |
|---|---|---|
| Managed Services | Limited internal staff | Full operational peace of mind |
| Co-managed DevOps | Growing internal teams | Shared knowledge and control |
| Project-based | Specific migrations | Cost-effective targeted expertise |
Set Up a Strong Cloud Management Foundation
Before handing over your cloud infrastructure, make sure your environment is organized. A messy setup makes effective outside support difficult. A clear baseline improves cloud infrastructure management and lowers the risk of costly errors.

Inventory accounts, environments, workloads, and dependencies
You cannot manage what you cannot see. Create a complete inventory of your cloud accounts, active workloads, and key dependencies. This discovery phase supports successful cloud migration and operational handover.
Standardize AWS, Microsoft Azure, or Google Cloud configurations
Consistency builds reliability. Whether you use AWS, Microsoft Azure, or Google Cloud, standardize configurations for predictable results. Standard setups help your outsourced team solve problems faster and deploy updates confidently.
Separate development, staging, and production environments
Keep testing environments separate from live production traffic. Strong isolation prevents accidental downtime and keeps your cloud infrastructure management secure. This separation supports high availability during your ongoing cloud migration journey.
Apply consistent naming, tagging, and ownership conventions
Clear labels help prevent confusion. Create strict naming and tagging rules for every resource you deploy. Assign ownership to each component, so your team knows whom to contact when a service needs attention.
Record architecture decisions and operational runbooks
Keep important knowledge in your documents, not only in engineers’ minds. Record architecture decisions and create step-by-step operational runbooks. These documents guide partners and explain the “why” behind your technical choices.
| Environment Type | Primary Purpose | Access Level | Data Sensitivity |
|---|---|---|---|
| Development | Feature testing | High (Developers) | Low |
| Staging | Pre-production validation | Medium (QA/Dev) | Medium |
| Production | Live customer traffic | Restricted (Ops/Admin) | High |
Build Infrastructure as Code and Reliable Deployment Workflows
Infrastructure as code turns your cloud environment from manual tasks into a reliable, version-controlled asset. Defining resources in text files makes your setup repeatable, reviewable, and easy to transfer between internal and outsourced teams. This approach prevents the “it works on my machine” problem in cloud operations.
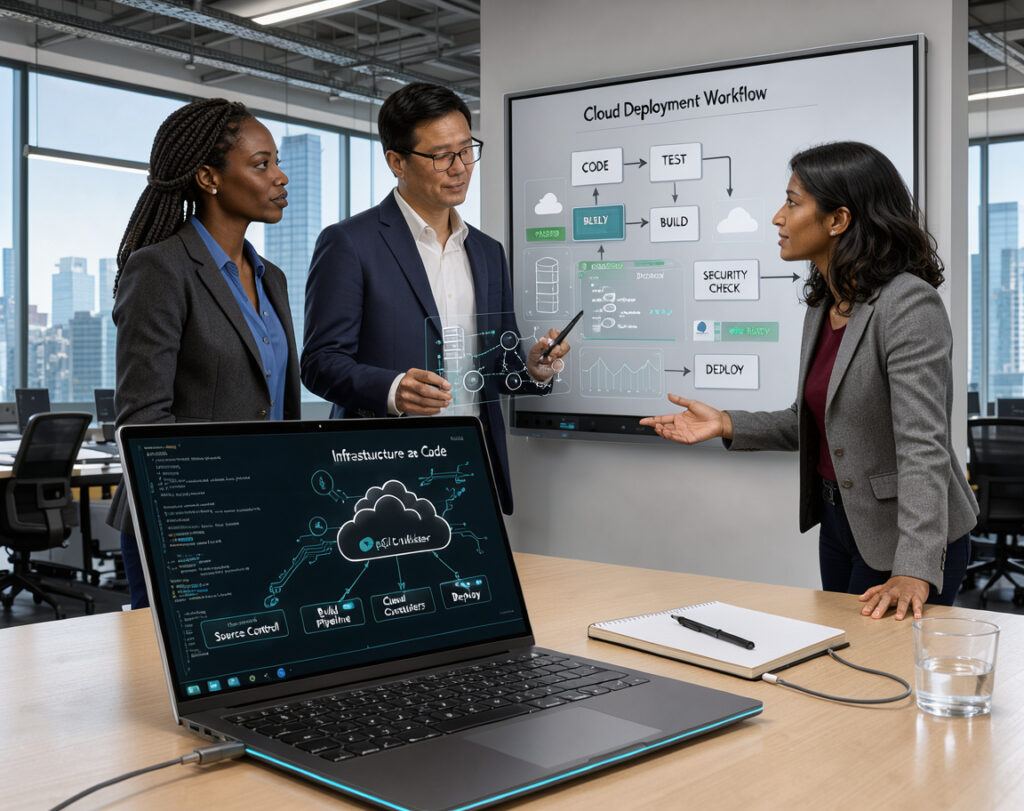
Manage repeatable infrastructure with Terraform or AWS CloudFormation
Choosing the right tool helps maintain a consistent cloud footprint. Terraform is popular because it works across cloud providers through one workflow. AWS CloudFormation provides deep, native integration for teams using the Amazon ecosystem.
“The goal of infrastructure as code is to treat your servers and networks with the same rigor as your application source code.”
Store infrastructure code in GitHub or GitLab
Store configuration files in a version control system like GitHub or GitLab. This creates a single source of truth for your cloud architecture. A repository records every change, making audits and rollbacks easier when problems occur.
Use pull requests and peer review for infrastructure changes
Peer reviews provide an important safety net for your cloud environment. Requiring a pull request ensures another engineer checks each change before production. This process catches errors early and shares knowledge across the team.
Automate plan, test, approval, and deployment stages
Automation drives reliable deployments. Use a CI/CD pipeline to run a “plan” phase that previews changes before application. Your team can check the impact, run tests, and gain approvals without manual work.
Protect state files, secrets, and production branches
Build security into your workflow from day one. Store state files in a secure, remote backend to prevent data loss and unauthorized access. Use protected branches and secret management tools to control production code and protect credentials.
- Version Control: Track every change to your infrastructure.
- Peer Review: Require human oversight for all production updates.
- Automated Testing: Validate configurations before they go live.
- Secret Management: Never hardcode passwords or API keys.
Secure Access, Data, and Cloud Workloads
When you hire an outsourced DevOps team, strong cloud security must be a top priority. Your partner must protect your infrastructure like an internal team and use safe configurations. Clear boundaries help prevent accidental exposure and unauthorized access.
Apply least-privilege identity and access management
Least privilege is the foundation of effective IAM strategies. Each user and service account should have only the permissions needed for its tasks. This limits the damage if one account is compromised.
Enforce multifactor authentication and privileged access controls
Passwords alone rarely stop modern threats. Require multifactor authentication (MFA) for every user who accesses your cloud console or command-line tools. Give privileged access temporarily, so high-level permissions stay active only when needed.
Protect secrets with AWS Secrets Manager, Azure Key Vault, or Google Secret Manager
Hardcoding credentials in source code creates a major security risk. Use services such as AWS Secrets Manager, Azure Key Vault, or Google Secret Manager for API keys and database passwords. These tools provide automated rotation and central audits, keeping sensitive data safe from prying eyes.
Review access permissions and service accounts regularly
Permissions can suffer from “privilege creep” as projects change. Your outsourced team should audit accounts monthly, remove unused ones, and narrow broad policies. Regular reviews keep your IAM setup lean and secure.
Encrypt data in transit and at rest
Data protection is essential in modern cloud environments. Encrypt all traffic between services with TLS, and use industry-standard encryption at rest for databases and object storage. Even if someone accesses physical storage, the information stays unreadable and protected.
| Security Control | Primary Benefit | Implementation Tool |
|---|---|---|
| Least Privilege | Limits blast radius | IAM Policies |
| Secrets Management | Prevents credential leaks | AWS/Azure/Google Vault |
| Data Encryption | Protects sensitive info | KMS / TLS |
| MFA Enforcement | Blocks unauthorized logins | Identity Providers |
Monitor Performance, Reliability, and Cloud Costs
Visibility builds a strong partnership with an outsourced DevOps team. When you delegate infrastructure management, partners must show your systems’ health clearly. Robust cloud monitoring helps verify service levels and keeps operations running smoothly.

Track infrastructure health with actionable observability
True observability goes beyond simple status checks. It collects deep insights into how applications interact with the cloud environment. By focusing on actionable data, your team can find bottlenecks before they affect end users.
Centralize logs, metrics, and traces with tools such as Datadog or Grafana
Fragmented data makes complex issues hard to troubleshoot. Centralized platforms like Datadog or Grafana let engineers combine logs, metrics, and traces in one view. This approach helps your outsourced team quickly find each performance problem’s root cause.
Define alerts that support fast investigation instead of alert fatigue
Constant notifications can cause burnout and hide critical issues. Configure alerts that provide meaningful, useful information. Filtering noise helps your team solve real problems instead of chasing false positives.
Measure uptime, latency, error rates, and resource saturation
To maintain reliability, track specific performance indicators. These metrics show system stability and support future growth planning.
- Uptime: Ensures your services remain available to customers.
- Latency: Tracks the speed of your application responses.
- Error Rates: Highlights bugs or configuration issues.
- Resource Saturation: Monitors CPU and memory usage to prevent crashes.
Use budgets, tags, and rightsizing to control cloud spending
Effective cloud cost optimization matters as much as technical performance. Strict budgets and resource tags show where your money goes. Rightsizing instances prevents you from paying for unneeded capacity.
| Strategy | Primary Benefit | Implementation |
|---|---|---|
| Resource Tagging | Cost Attribution | Automated scripts |
| Rightsizing | Waste Reduction | Performance analysis |
| Budget Alerts | Spending Control | Cloud provider tools |
Run Incident Response and Disaster Recovery
Preparing for the worst helps keep your business online during a crisis. When you outsource cloud management, treat incident response as a shared effort with your provider. A shared strategy tells your internal team and external partners how to react when systems fail.
Create an incident response process before an outage occurs
You cannot build a plan while services are down. A clear, documented workflow helps your team act with confidence instead of panic. It should list steps to identify, contain, and resolve issues as soon as they appear.
Set severity levels, communication paths, and escalation timelines
Not every technical glitch needs an emergency response. Clear severity levels send resources to the most critical problems first. Your communication plan should name people to notify and channels such as Slack, email, or phone calls.
- Severity 1: Critical system outage affecting all users.
- Severity 2: Partial service degradation or performance issues.
- Severity 3: Minor bugs or non-urgent maintenance needs.
Define backup, restoration, and failover requirements
A strong disaster recovery strategy supports cloud resilience. Define how often data is backed up and how quickly backups can return to production. Automated failover should shift traffic to healthy environments without manual intervention.
Test recovery point and recovery time objectives
Recovery Point Objectives (RPO) and Recovery Time Objectives (RTO) are more than spreadsheet numbers. They show the maximum data loss you can tolerate and the longest time you can remain offline. Test these objectives with your provider regularly to confirm actual performance meets business requirements.
Conduct blameless post-incident reviews and track corrective actions
After resolving an incident, focus on learning and improvement. A blameless post-incident review lets team members explain what happened without fear of punishment. Tracking corrective actions turns each outage into a chance to strengthen infrastructure and prevent future occurrences.
Scale Cloud Infrastructure Without Losing Control
Scaling cloud infrastructure can challenge growing businesses, but it does not need to become chaotic. An outsourced DevOps team builds Kubernetes systems that handle traffic spikes automatically and reliably. Smart automation keeps your platform stable as your user base grows quickly.
Automate capacity changes with autoscaling and infrastructure policies
Manual intervention during traffic surges can cause downtime. Your team should implement autoscaling policies that adjust resources using real-time CPU, memory, or request metrics. The environment grows during peak hours and shrinks during quiet periods, helping control monthly cloud spending.
Prepare for traffic growth, geographic expansion, and new workloads
Proactive capacity planning supports long-term success. Outsourced experts forecast demand by studying historical data and upcoming marketing campaigns. They also design multi-region Kubernetes architectures that place services closer to global customers, reducing latency and improving user experience.
Use Kubernetes when container orchestration justifies its complexity
Kubernetes manages containerized applications, but it also adds significant operational work. Adopt it only when your workload needs advanced orchestration, such as managing hundreds of microservices. For simpler applications, managed container services often offer better value without a steep learning curve.
Set scaling limits to prevent runaway usage and costs
Unchecked automation can create unexpected billing surprises. Always define hard scaling limits in your infrastructure policies as a safety net. These guardrails stop your environment from starting too many resources after a configuration error or malicious traffic spike.
Review architecture before major product or traffic milestones
Before launching a new feature or entering a high-traffic season, conduct a thorough architecture review. This process finds bottlenecks that automated systems might miss. By validating your Kubernetes design early, you ensure infrastructure supports business goals without sacrificing performance.
Manage Communication, Documentation, and Vendor Accountability
Keeping your cloud infrastructure transparent supports successful partnerships with external DevOps providers. When you delegate cloud operations, keep a clear view of daily work so systems stay secure and efficient.
Set a practical cadence for operational reviews
Regular meetings keep both parties aligned with project goals. A weekly or bi-weekly sync helps you review tasks and fix bottlenecks before they become major issues.
These sessions should focus on strategic alignment, not only status updates. Consistent reviews build trust and help the vendor understand changing business needs.
Keep runbooks, diagrams, inventories, and credentials documentation current
Documentation supports reliable infrastructure. Update runbooks, network diagrams, and asset inventories whenever your environment changes.
Protect credentials with strict security rules. Use a centralized vault, and give your team and the vendor only the access their roles require.
Use dashboards and reports to make outsourced work visible
Visual data connects internal stakeholders with external engineers. Use real-time dashboards to track system health and the efficiency of your cloud operations.
Standardized reports show performance over time. They should highlight key metrics that prove the value the vendor brings to your organization.
Review service-level agreement performance and unresolved risks
An SLA supports your professional relationship. Review these metrics monthly to confirm the provider meets uptime and response time commitments.
Set aside time to discuss unresolved risks. Finding them early helps you reduce threats to infrastructure stability.
Require clear handoffs between the provider and internal stakeholders
Clear handoffs prevent information silos. When work moves from the vendor to your internal team, transfer all relevant context and technical details.
| Communication Method | Purpose | Frequency |
|---|---|---|
| Operational Review | Align strategy and review SLA | Bi-weekly |
| Dashboard Monitoring | Track cloud operations health | Real-time |
| Documentation Audit | Verify accuracy of runbooks | Quarterly |
Measure the Success of an Outsourced DevOps Team
Assessing an external partner requires more than checking whether tasks are complete. Ensure your cloud environment stays stable, secure, and aligned with long-term business goals. Using the right DevOps metrics gives you a clear view of your outsourced team’s value.
Track reliability, deployment, recovery, and security metrics
Reliability supports every successful cloud strategy. Monitor uptime percentages and error rates to keep your infrastructure dependable for end users. Deployment frequency shows how often your team delivers value, while recovery metrics show response speed after unexpected issues.
Security metrics help maintain a strong security posture. Audit access logs regularly and watch for unauthorized configuration changes to protect your data. These quantitative indicators provide factual evidence about your cloud operations’ health.
Evaluate productivity without rewarding unsafe speed
Rapid deployments may seem attractive, but speed without quality often creates technical debt. Avoid incentives that push your team to rush changes into production and weaken stability. Instead, promote sustainable productivity through thorough testing and peer reviews.
Pressure to move too fast can cause your team to skip key security checks or documentation. A healthy partnership rewards consistent, high-quality work that reduces risk. This approach helps your infrastructure scale reliably as your business grows.
Connect DevOps outcomes to customer experience and business goals
Your cloud infrastructure ultimately exists to support customers. Use DevOps metrics to connect technical performance data with user outcomes, such as page load times and feature availability. When outsourced teams understand their effect on the bottom line, they become true business partners.
Use change failure rate and mean time to recovery responsibly
Change failure rate and mean time to recovery (MTTR) help measure operational maturity. Use these numbers to find improvements, not punish the team. Build a learning culture where the team discusses failures openly and adds better safeguards.
Reassess objectives as the company and infrastructure mature
Your needs will change as your company scales and your cloud footprint expands. An approach that worked during your initial migration may fail with a complex, multi-region architecture. Review DevOps metrics and performance benchmarks regularly so they match your current growth stage.
| Metric Category | Primary Goal | Key Indicator |
|---|---|---|
| Reliability | System Uptime | Service Availability % |
| Deployment | Efficiency | Change Failure Rate |
| Recovery | Resilience | Mean Time to Recovery |
| Security | Protection | Patch Compliance Rate |
A Practical Transition Plan for Outsourced Cloud Operations
When you outsource DevOps, the handoff shapes your long-term operational stability. A structured approach helps your team keep control while gaining external expertise. This process often supports a broader cloud migration strategy.
Document the current state before transferring responsibility
Before changes begin, create a complete map of your environment. This map should list all cloud accounts, active workloads, and hidden dependencies that keep your applications running.
Clear documentation prevents knowledge loss during the transition. Your internal team should record current configurations, security policies, and architectural diagrams. This gives the incoming team a solid foundation.
Start with a controlled discovery and stabilization phase
The initial phase finds immediate risks and performance bottlenecks. By auditing your setup, the outsourced team can fix urgent issues before taking full control.
This stabilization period is vital for a successful cloud migration. It helps both parties set priorities and fix critical vulnerabilities without disrupting daily business operations.
Move recurring operations into documented managed workflows
Once the environment is stable, shift routine tasks into standard processes. This includes daily monitoring, patch management, and routine scaling activities.
Using repeatable workflows ensures consistency, no matter who performs the task. It also makes performance easier to track and helps identify areas for future automation.
Validate access, monitoring, backups, and incident response before handoff
Before the final handoff, verify that every safety net works properly. Test backup restoration procedures and ensure monitoring alerts reach the correct personnel.
Confirm that access controls follow the principle of least privilege. Security validation is non-negotiable when administrative rights move to an external provider.
Use a phased transition to reduce production risk
Avoid a “big bang” approach by moving services in smaller, manageable batches. This lets you monitor each change and adjust your cloud migration plan as needed.
Phased rollouts provide a safety buffer. If an issue arises, you can isolate it quickly without affecting the entire infrastructure.
Define exit, knowledge-transfer, and continuity requirements
Always plan for the engagement’s end from the very beginning. Set clear protocols for transferring knowledge back to your team if the contract concludes.
Maintain a continuity plan with regular documentation updates and periodic reviews. This keeps your business resilient and independent over the long term.
| Phase | Primary Goal | Key Deliverable |
|---|---|---|
| Discovery | Identify Risks | Infrastructure Audit |
| Stabilization | Fix Bottlenecks | Optimized Environment |
| Operational Handoff | Transfer Control | Validated Workflows |
| Continuous Review | Ensure Quality | Performance Reports |
Conclusion
Building a resilient digital environment requires a clear, long-term strategy. Learning how to manage cloud infrastructure requires balancing ownership, secure access, and automated workflows. An outsourced DevOps team can bring major advantages to your existing business model.
These experts provide observability and recovery planning to keep your systems running smoothly. You can scale operations without building a massive in-house department from scratch. Knowing how to manage cloud infrastructure lets internal staff focus on core product development while partners handle technical heavy lifting.
Your path forward begins by selecting an engagement model that fits your current growth stage. A clear transition plan helps your team maintain control over critical assets.
Prioritize clear communication and measurable outcomes to keep your cloud environment secure and efficient. Start your journey today by matching your operational maturity with the right support structure for your business goals.